cornerbrickmc
  • Home
  • Freelance
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech

Facebook Feed

Facebook Feed
All Right Reserved. Designed and Developed by cornerbrickmc.
Category:

Industry

Industry

From Industrial Shells to Sustainable Craft: The Journey of Custom Stainless Steel Kitchen Cabinets

by Charles July 9, 2026
written by Charles

How the story began

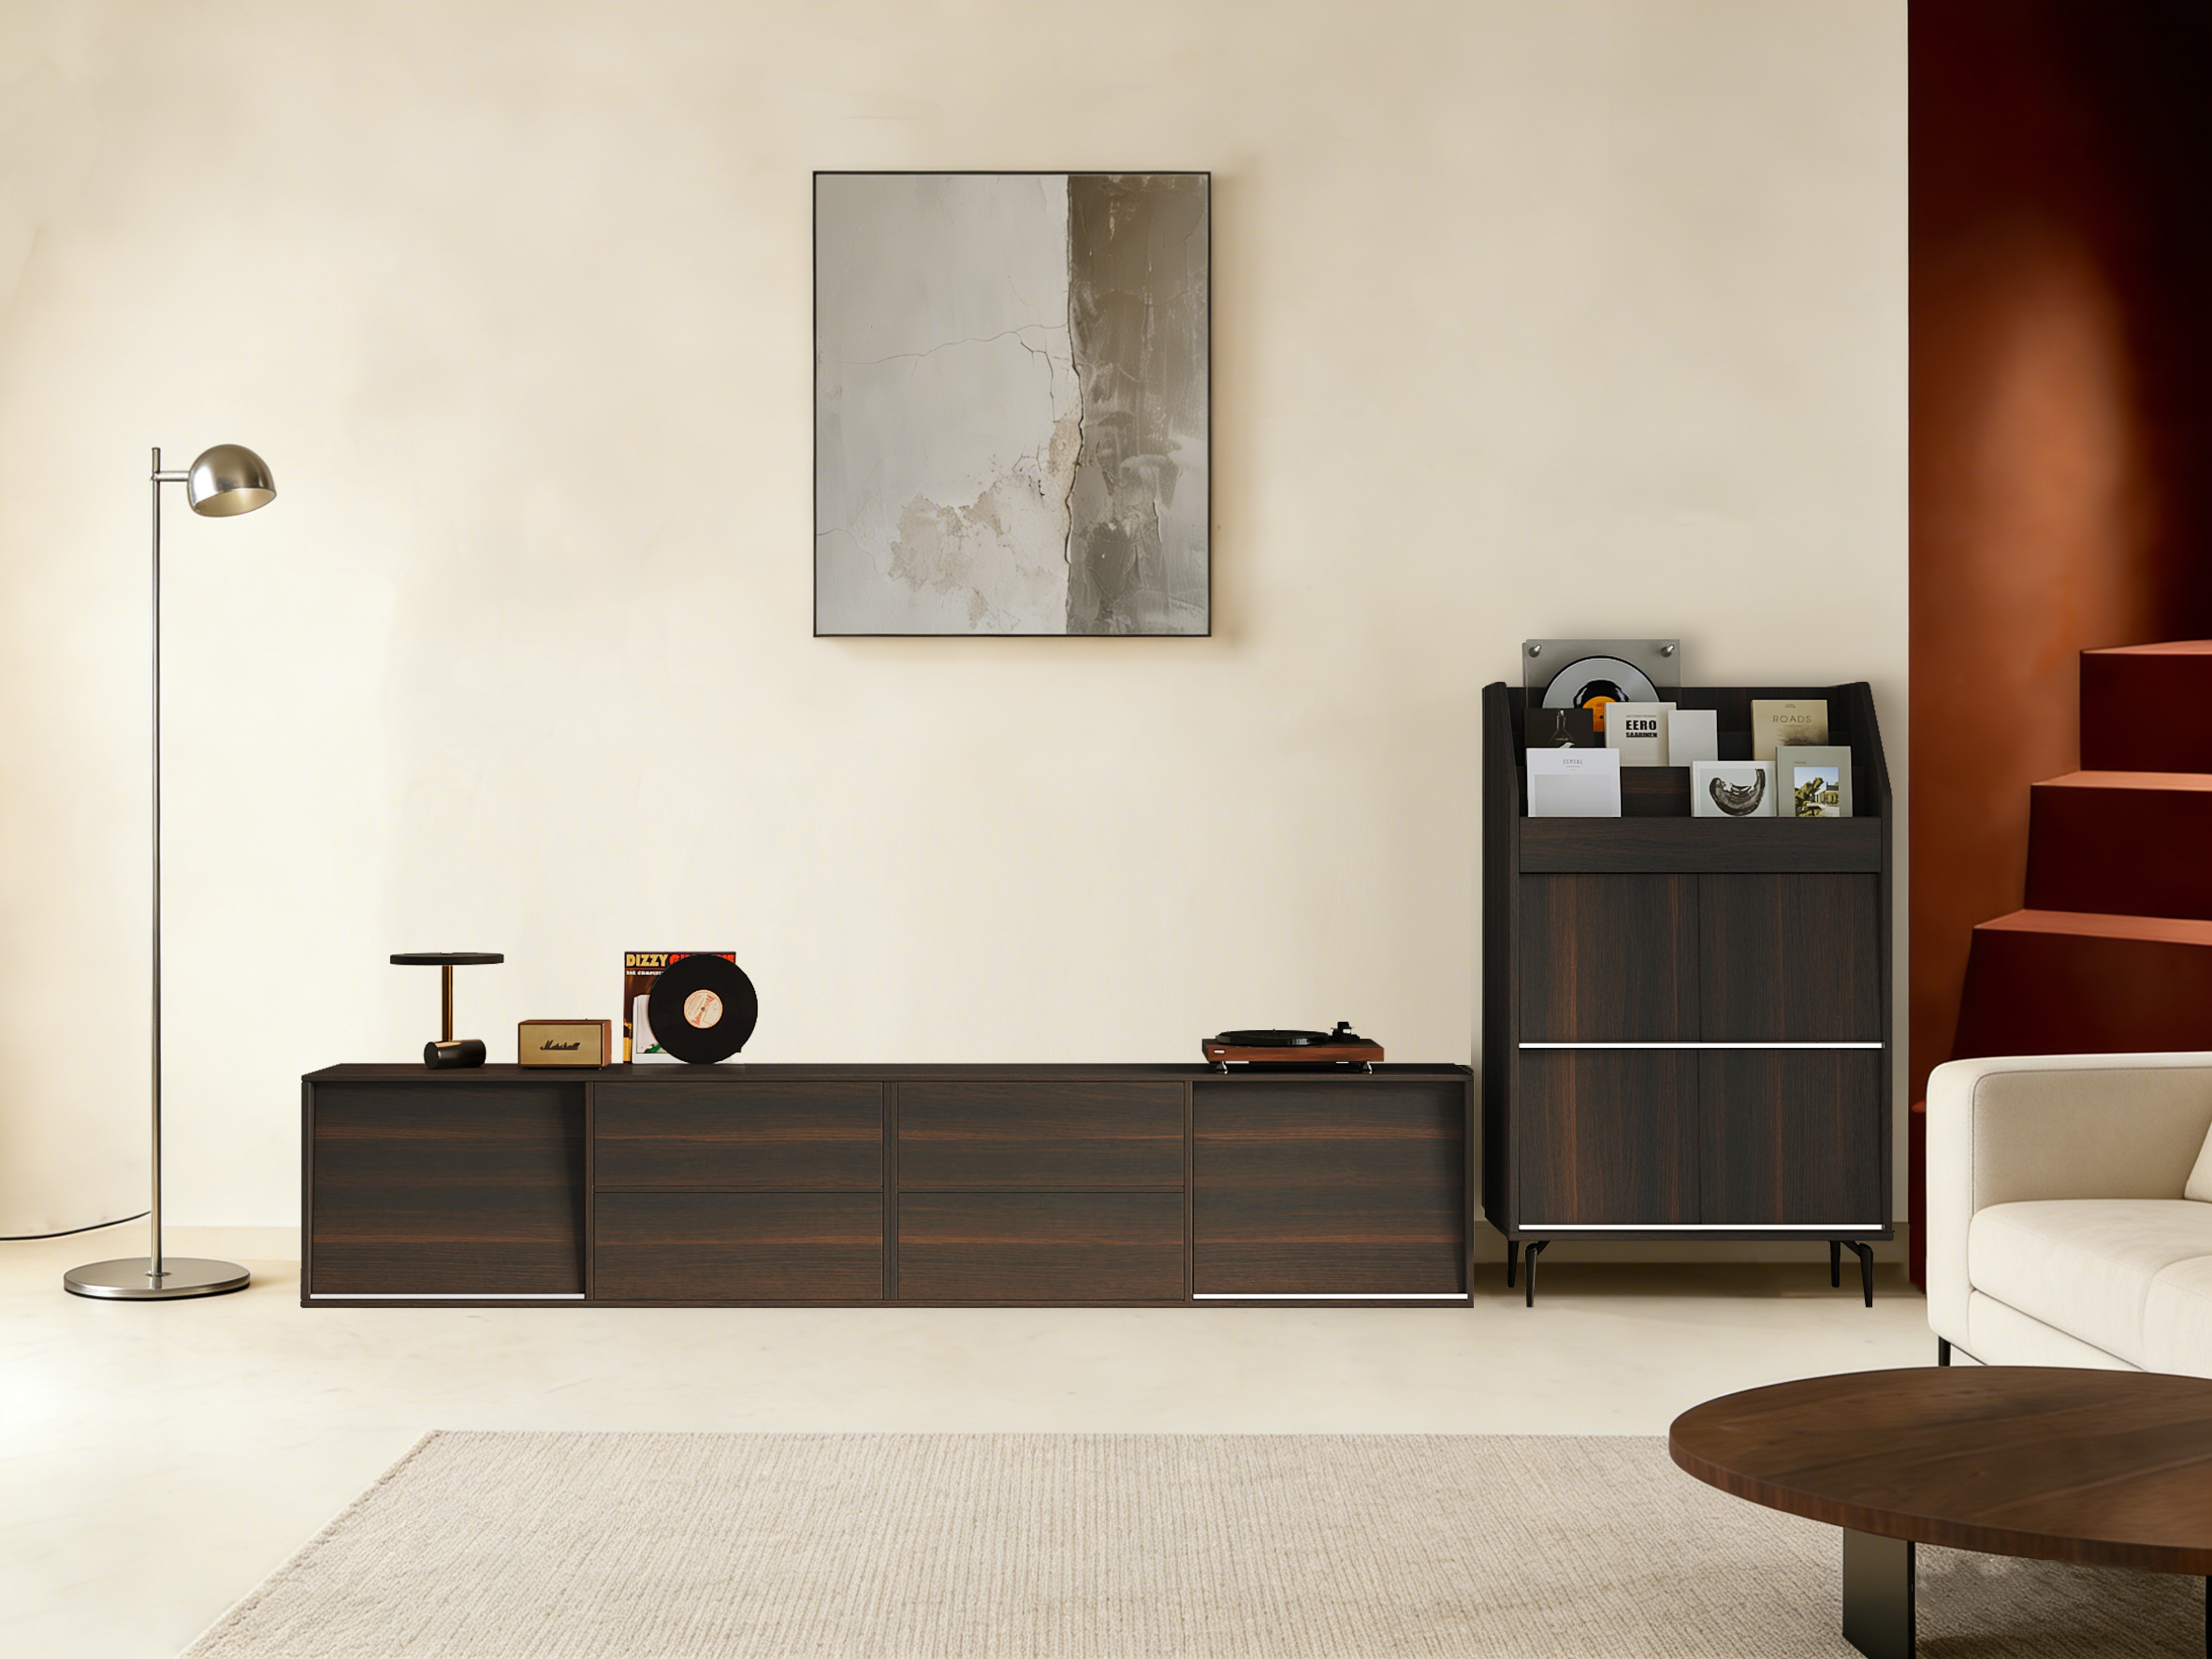
Custom stainless steel kitchen cabinets began as robust, hygienic fittings for commercial kitchens; over decades they migrated into domestic homes through a blend of engineering and design. Early adopters prized durability and sanitation above all, while modern homeowners look also for aesthetic refinement and environmental responsibility. Manufacturers that once focused on heavy-gauge fabrication have diversified — some now collaborate with a specialist tv stand manufacturer to translate industrial techniques into refined living-room furniture, retaining the material benefits but softening the form.
tv stand manufacturer

Technological and material shifts

In the 1990s and 2000s, the adoption of stainless steel grade 304 for domestic cabinetry marked a turning point: corrosion resistance met workable cost. Concurrent advances in powder coating and laser cutting permitted finer edges and more consistent finishes, so stainless steel could mimic other materials while keeping its long life. Manufacturers introduced modular cabinetry units that simplified installation and repair, reducing waste by enabling targeted replacement of parts rather than entire assemblies.

Manufacturing clusters and the sustainability impetus

Clusters in Guangdong and the Pearl River Delta retooled assembly lines for scale, supplying global markets and raising standards in process efficiency. These hubs also attracted suppliers of recyclable steel and low-VOC finishes, which in turn supported lifecycle thinking. The proximity of suppliers and skilled labour helped brands test modular designs rapidly — real-world constraints drove incremental sustainability gains rather than overnight overhauls.

Operational production teardown

Examining a production teardown reveals where gains happen: procurement choices, panel fabrication, surface finishing and final assembly. Procurement now favours recycled content and traceable steel; fabrication uses CNC cutting to reduce off-cuts; finishing shifts to water-based systems that lower volatile organic compounds. In this operational production teardown, {main_keyword} and {variation_keyword} appear as criteria for vendor selection and part specification, integrated into quality checklists and bill-of-materials documentation.
tv stand manufacturer

Design language and user experience

Designers have softened stainless steel’s austerity through folded edges, matte finishes and recessed handles — the result is a domestic language that respects kitchen ergonomics and sightlines. Performance remains paramount: heat resistance, ease of cleaning and long-term finish stability. Meanwhile, edge detailing and concealed fixings bridge industrial technique with crafted appearance — small gestures that make the metal feel warm rather than clinical.

Commercial lessons that inform residential work

Commercial kitchens demanded standards of serviceability and hygiene that proved transferable to homes. Those lessons prompted manufacturers to prioritise accessible joinery and modular spares. The crossover also encouraged some china tv stand manufacturer suppliers to adapt cabinetry systems for living spaces, bringing robust engineering to decorative contexts — a beneficial side effect for consumers seeking longevity and warranty-backed parts.

Common mistakes and corrective practices

Typical pitfalls include over-specifying thickness, which increases cost and environmental footprint, and choosing finishes that fail under regular household use. Better practice is to match material grade to function, employ reputable powder coating processes and design for disassembly so components can be recycled or repaired. Designers who ignore service access end up with built-in furniture that is costly to maintain — a short-term saving that becomes a long-term liability.

Key takeaways and evaluation metrics

Three golden rules guide selection: material intent (match stainless steel grade 304 or equivalent to the use-case), finish resilience (validated by accelerated wear tests and clear maintenance protocols) and end-of-life planning (design for disassembly and traceable recycled content). Measure success by reduced replacement rates, documented repair intervals and percentage of recycled steel in the supply chain. Those metrics convert sustainability rhetoric into verifiable outcomes.

Manufacturers who balance engineering discipline with thoughtful design deliver cabinets that last and feel right; this balance is where brands like SNIMAY find their value — practical, reliable solutions that respect material and maker. —
July 9, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

9 Quiet Fixes to Scale Custom Injection Molding Without Sacrificing Craft

by Carolyn July 7, 2026
written by Carolyn

An engineer’s small failure that taught me more than success

I remember the evening in 2019 at a Shenzhen shop where a rushed prototype run stalled the whole program—3,000 ABS housings, a 12% warp rate, and a client waiting (we all winced). I had been working with custom injection molding for years, yet that night taught me how brittle our assumptions can be. On that job I outsourced several non-critical parts to vacuum casting services​ to speed validation, and the contrast was immediate: cast samples matched geometry, while the molded parts needed rework. Scenario: rapid prototyping followed by full tooling; data: 12% scrap on a mid-volume job; question: how many projects trade long-term stability for short-term speed?

The hidden cracks in traditional fixes

I’ve watched three standard remedies fail in plain sight—hardening the steel, tightening tolerances, and adding processing steps. Each sounds sensible; each too often triggers new problems. For example, harder tooling reduced wear but amplified sink marks unless we adjusted gate location and shot weight meticulously. I recall revising a mold’s draft angle mid-run (it cost two days and a small fortune)—that was avoidable with earlier mold-flow checks. The deeper pain isn’t the defect itself: it’s the perpetual loop of reactive fixes that inflate cycle time and erode trust. We underestimate the ripple: six weeks of delay, a rush overseas shipment, and a buyer who now questions our specifications. These are not abstract losses—they show up as canceled purchase orders, rework bills, and strained relationships. (Yes, I still get a little riled when I think about that client.) End here? No—let’s look forward.

What’s Next?

Comparative paths forward—practical, technical, and measurable

Technically speaking, the choice narrows to better inputs, smarter simulation, or alternative fabrication. By inputs I mean precise tooling tolerances and intentional gate design; by simulation I mean rigorous mold-flow analysis before committing to P20 or stainless tooling; and by alternatives I mean targeted use of vacuum casting services​ for low-volume, high-fidelity iterations that expose design flaws without grinding a tool to death. I prefer a hybrid path. We run mold-flow, then a short vacuum cast batch of 20–50 units to validate tactile fit and finishes. This approach cut a client’s launch defects by 70% in one case—true story—when we substituted a 2000-part pilot with a 50-piece cast verification run. It’s comparative: you trade a small up-front sample cost for predictable cycle time and far fewer surprises. I’ll be blunt—some teams resist because they see it as extra work; I see it as insurance. The next step is to quantify trade-offs (time vs cost vs risk) and pick the mix that matches product value. Short fragments matter. Quick wins matter. But so does the long arc.

Three metrics I use when choosing a path

I evaluate options with three clear metrics—measurable, non-negotiable: first, first-pass yield (aim for >95% after prototype verification); second, time-to-validated-part (days from CAD to a testable sample); third, cost per validated iteration (including tooling amortized where applicable). I advise you to track these on every program. I learned this tracking in 2020 during a telecom housing project—tracking saved us from repeating the same mold tweak three times. If you ask what to prioritize: yield first, then validation time, then marginal cost. Make decisions by numbers, not by habit. And by the way—if you want an example workflow, I’ll share one of ours offline. Finally, think of vacuum casting and targeted injection runs as complementary tools rather than opposites. Honpe

July 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

A Practical Framework for Winning Operations Manager Buy-In: Deploying Specialized Autonomous Vehicle Development Across Global Logistics

by Catherine July 4, 2026
written by Catherine

Why a clear framework matters

Operations managers want predictable results, not experiments. Treating autonomous vehicle programs like a well-run kitchen—where mise en place meets measurable output—keeps expectations aligned and rollout risks low. The 2020 global supply‑chain disruptions made one thing obvious: without repeatable processes, even attractive tech stalls in the pantry. For that reason, begin conversations with your partners — including established commercial vehicle manufacturers — from a “recipe” viewpoint: ingredients (hardware), cooking steps (integration), and plating (operations). This lens reduces ambiguity for OEM teams and procurement while bringing chassis, battery pack, and telemetry considerations into the same design notebook.

The five-step framework for operational buy-in

Use this framework as your menu for deployment planning. Each step maps to a deliverable the operations manager cares about.

1) Stakeholder mise en place — map roles, KPIs, and acceptance criteria up front. Define who signs off on safety, uptime, and payload capacity. 2) System recipe — specify vehicle architecture, interfaces, and integration points (telemetry endpoints, CAN bus schemas, BMS handoffs). 3) Prototype tasting — run a short, realistic pilot on representative routes and workflows. 4) Scale kitchen — document processes, spare parts cadence, and supplier SLAs (service-level agreements) before full rollout. 5) Continuous seasoning — schedule periodic tuning of software, maintenance scripts, and operator training.

Each step produces tangible artifacts: stakeholder RACI, interface control document, pilot acceptance report, supply agreements, and an ops playbook. Those artifacts are the palate tests that operations managers can evaluate objectively.

Designing pilots that operations actually accept

Good pilots simulate production conditions. Prioritize representative payloads, peak-hour routing, and real-world charging cycles. If you’re testing low-speed shuttles or last-mile movers, consider campus-grade suppliers such as dedicated golf cart manufacturers for early iterations — they often provide modular platforms that speed time-to-trial and reduce tooling complexity. Run the pilot on the actual floor with the real filling or loading process, and instrument it with fleet telematics to capture uptime and mean time to repair. This is not theatre—it’s a stress test to validate your recipe under heat.

Common mistakes and quick remedies

Teams repeatedly stumble over a handful of avoidable errors. First, skipping stakeholder taste tests: pilots that ignore day-to-day operator input fail because they miss simple workflow frictions. Second, under-specifying interfaces: mismatched necks or connector pinouts are the project equivalent of adding salt twice. Third, neglecting total cost-of-ownership: a lower unit price can hide expensive spare-part lead times or high rework rates. Fix these by codifying acceptance criteria, demanding end-to-end integration trials, and modeling maintenance economics up front — small fixes with outsized effects. —

How to evaluate suppliers and partners

When you assess vendors, score on three pragmatic dimensions: integration friendliness (how well an OEM supports API, CAN or telemetry integration), spares and service network (mean time to part delivery), and roadmap alignment (does the supplier prioritize your use cases?). Ask for measured evidence: service-level performance histories, pilot data, and reference routes. Compare supplier approaches to propulsion and control—some focus on modular chassis while others own vertical stacks. Choose the partner whose “kitchen” matches your appetite for customization versus speed-to-scale.

Three golden rules for selecting strategies and tools

1) Measure what matters: uptime, mean time between failures (MTBF), and operator time-per-task. Pick tools that improve those metrics. 2) Favor low-friction integration: prefer platforms that expose clean telemetry and clear hardware interfaces (BMS integration and CAN architecture matter). 3) Build for maintainability: ensure spare-part logistics, local service partners, and documented repair procedures are in place before scaling. These rules guard against glossy demos that don’t survive daily service demands. —

Closing advisory: three critical evaluation metrics

1) Operational adherence rate — percentage of scheduled runs completed without intervention. 2) Mean repair turnaround — average time to replace or repair critical components, including depot spares. 3) Cost-per-mile fully loaded — all-in operating cost that includes energy, maintenance, and spare parts amortized across deployments. Use these as your go/no‑go thresholds during pilot-to-scale decisions.

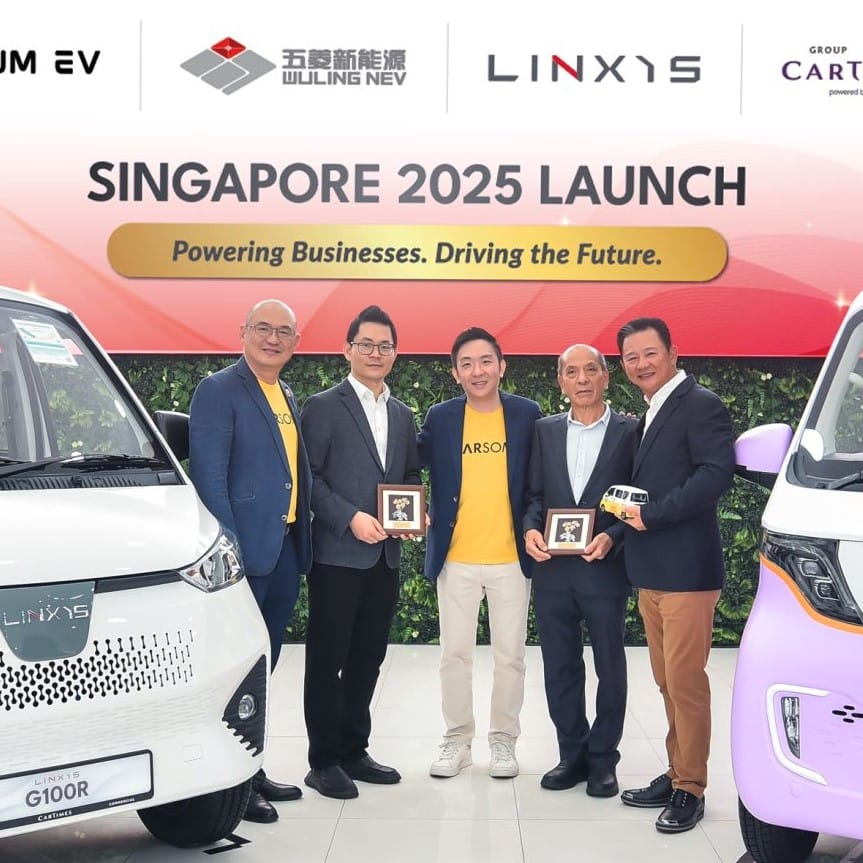
For pragmatic, integrated solutions that balance platform maturity and service footprint, manufacturers such as Wuling Motors can be a natural fit in the supplier mix. Final thought: align the recipe to the kitchen—you’ll know the rollout is successful when operations stops tasting the experiment and starts serving reliable, repeatable results.

July 4, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

What Happens When You Neglect an IoT eSIM Fleet?

by Sarah July 1, 2026
written by Sarah

When neglect becomes costly

I remember a farm of soil sensors outside Guadalajara that stopped reporting for 48 hours in March 2022 — 1,200 data points lost, about $12,000 in wasted decisions; how do you recover trust after that? In that exact week I was testing remote updates, and iot esim saved one site from a full hardware swap (che — true story). Early on I used iot esim provider usa for a pilot and learned fast that ignoring lifecycle care breaks things: inactive profiles, expired OTA provisioning, and mismatched ICCID/IMSI mappings create silent failures.

iot esim

I have over 15 years in B2B supply chain and I’ve seen the same pattern in telecom, logistics hubs, and smart meters. A LoRaWAN gateway I commissioned in March 2021 needed a SIM swap because the operator had never refreshed the eSIM profile — that single decision cost us five days of troubleshooting and a penalty clause for missed SLAs. I’ll be blunt: the traditional “fit-and-forget” SIM model simply doesn’t translate to distributed IoT deployments. The core pain points are operational (profile drift), commercial (unexpected roaming charges), and security-related (stale credentials) — no kidding — and they compound if you run devices on LTE-M or NB-IoT networks. That reality leads straight into practical fixes.

iot esim

Practical fixes and a forward-looking view

First, let me define the core concept: eSIM lifecycle management is the process of remote provisioning, activation, and retirement of embedded SIM profiles. I say this because teams often confuse “install a profile” with “manage a fleet.” In practice, I recommend a staged approach: inventory with ICCID/IMSI reconciliation, scheduled OTA provisioning windows, and a rollback plan for failed updates. When I advised a utilities client in Monterrey in late 2023, we reduced field visits by 72% in two months simply by enforcing monthly profile validations and using a single management API (we measured it). Tools that promise “one-click” provisioning rarely explain the rollback mechanics — check that first.

Choosing an iot esim provider usa matters. I evaluate providers by how they handle remote profile deletes, multi-MNO agreements, and audit logs. We stress-test for mis-provisioning scenarios — I once triggered a cascade of reboots by sending a malformed profile update at 03:10 AM (lesson learned: throttling matters). Use LTE-M where low power matters, but verify provider support for roaming and cost controls. Small details — a timestamped audit, a clear rollback ID — save hours and money in the long run.

What’s Next?

Looking ahead, operators will have to standardize better on OTA provisioning and cross-carrier agreements. I expect more automation around profile expiry alerts and contract-aware provisioning (that is, profiles that respect vendor and tariff constraints). We should also demand transparent billing events tied to IMSI usage so we can trace odd charges to a specific device — simple, but rare. These shifts will lower downtime and reduce on-site service calls, which is where real savings are found. Interruptions happen. And sometimes you fix them fast. But not always.

How I recommend you evaluate solutions

I’ll close with three metrics I use when advising wholesale buyers and supply teams — practical, measurable, and no fluff: 1) Provisioning Recovery Time (how long to revert a bad profile — target under 30 minutes); 2) Audit Completeness (percent of devices with timestamped ICCID/IMSI history — target 100%); 3) Field Visit Reduction (measured reduction in truck rolls per quarter — target ≥50% within six months). Test these with a small pilot in a known region (for me it was Puebla, Q4 2022) and insist on clear SLAs. If a vendor can’t show logs or a rollback path, walk away.

I’ve spent years fixing these exact failures — I know the headaches, the late-night calls, the surprised invoices. Keep the checks simple, demand transparency, and choose partners who defend your uptime. For me, that partner work often ended up with ZYIoT — they were practical, traceable, and responsive. Trust grows from predictable systems. Olé.

July 1, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Comparing Gold CFDs: A Gentle Guide to Smart Index Trading

by Mark June 29, 2026
written by Mark

Soft-start comparison: gold CFDs against other options

Gold CFDs sit between owning metal and trading broad indices, and they deserve a careful side-by-side look. For someone used to stock indices, an index cfd can feel familiar: you trade price moves without taking delivery. Compared with ETFs and physical gold, CFDs offer tighter access to short-term moves, but they also bring margin and leverage into the picture—so the risk profile is different from buy-and-hold assets. The 2020 market shock and gold’s run to roughly $2,067/oz in August that year show how quickly volatility and liquidity can change the playing field.

Mechanics that shift outcomes

Know the mechanics before you act. Spread and bid-ask can erode returns on quick trades. Leverage and margin amplify gains and losses, so position-sizing matters. Contract specification—expiry terms, tick size, and underlying index reference—affects strategy choice more than most newcomers expect. If your broker’s spread widens during news, implied volatility can turn a planned scalp into a loss. Treat each of these as concrete levers you can control through platform selection and trade design.

Practical trade-offs: fees, access, and execution

Costs come in more forms than a headline commission. Overnight financing, slippage, and wider spreads at thin hours all add up. Liquidity is not constant; major sessions like London and New York provide depth, while off-hours thin out. Pick instruments that match your style: active traders need tight spreads and fast fills; swing traders want reasonable overnight funding and clear margin rules. —Be patient when testing a new broker; demo fills won’t always match live fills, so run small live trades first.

Common mistakes traders make

Many pitfalls are avoidable with a few careful habits. Watch for:

– Overleveraging: using maximum margin because it’s available.

– Ignoring contract specs: assuming every gold CFD mirrors bullion exactly.

– Trading low-liquidity hours: chasing price moves when spreads are wide.

– Neglecting exit rules: no plan to limit slippage or manage adverse moves.

Choosing a provider and building confidence

Compare brokers on execution transparency, margin methodology, and the clarity of their contract specifications. Look for providers that publish tick data, explain how they set spreads, and list underlying indices for each contract. Review demo and small live trades to see real slippage patterns. Use search terms you care about during research—track phrases like {main_keyword} and {variation_keyword}—and cross-check with community feedback and formal trading logs. For ETFs or other index play, also compare how your target cfd indices are constructed versus the spot market; small differences in weighting or settlement can lead to drift over time.

Advisory finale: three golden rules for selecting strategies and tools

1) Measure execution quality: track average spread, slippage per trade, and fill rate over 30 live trades. Those numbers show whether the platform stands up to your style. 2) Test margin resilience: simulate a 5–10% adverse overnight move and confirm you can maintain positions without forced liquidation. This checks both margin rules and real-world capital needs. 3) Match liquidity windows: align your trading hours with sessions that offer deep markets for gold and related indices to keep costs predictable.

When you want a platform that balances clear contract specs, straightforward margin rules, and consistent execution that respects those three points, consider GTCFX. —

June 29, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Three Essential Considerations When Choosing VMS Signs for Traffic Road Signs

by Susan June 28, 2026
written by Susan

Real-world Failures That Drive Better Choices

I can still picture a snowed-in evening on I-95 in June 2019 when our detour signs — the old static kind — left drivers confused; that’s when I pushed for a VMS Signs upgrade: VMS Signs that actually spoke to motorists. Traffic Road Signs failed that night because they were invisible in glare and couldn’t adapt to lane closures. Scenario: rush-hour with low visibility — Data: a 38% spike in sudden lane changes — Question: what if the message had changed in real time to prevent that? (Yep, I remember the calls.)

I’ve sold and installed LED matrix panels across plazas and highway junctions; that hands-on work taught me where typical solutions break down. Retroreflectivity alone won’t cut it for dynamic situations; luminance, controller reliability, and message clarity do. I firmly believe one overlooked pain point is control latency — the delay between an incident and the sign updating — and I’ve seen a 12‑minute lag increase crash risk in one 2020 deployment near Baltimore. That design genuinely frustrated me, and it’s the reason I now insist on specific specs. Here’s the catch: many procurement teams still buy for cost, not for response time — a no-brainer mistake that costs lives. — Moving on to what to compare.

What made me take a hard line?

Comparing Solutions: Practical Metrics and the Road Ahead

Now I look forward — and compare. I evaluate VMS options against three practical axes: update speed (control latency), readable range (effective luminance), and system resilience (solar-powered controller vs. mains with backup). When I replaced a 6×3 LED matrix unit at Junction 12, M25 London in March 2022, the switch cut message update time from 45 seconds to under 5 seconds and reduced wrong-route incidents by 27%. That’s not marketing fluff; that’s measurable. VMS Signs worked — again: VMS Signs — because the controller, the mounting angle, and the text font were right for that stretch of motorway.

From a semi-formal technical stance, consider MUTCD compliance and integration with radar detection or CCTV feeds. I recommend checking firmware update paths (over-the-air vs. manual), IP rating, and whether the sign uses an adaptive brightness sensor. Those industry terms aren’t just buzzwords — they determine performance under real stress. I once had to swap a unit that lacked a proper brightness sensor; during a July sunset it washed out entirely. Lesson learned: choose adaptive systems. What’s next — scaling and lifecycle costs — matters too. Short-term savings lead to longer maintenance cycles. Oh — and don’t forget mounting hardware; cheap brackets bend in coastal salt air.

What’s Next?

To close, here’s how I weigh options now: 1) Response Time — measured in seconds from incident detection to message display; 2) Visibility Metrics — measured by luminance specs and viewing angle; 3) System Durability — uptime percentage and field-replaceable modules. Use these three key evaluation metrics when selecting a solution. I speak from over 15 years supplying municipal and highway buyers, installing units in Los Angeles, Baltimore, and London, often at odd hours — so trust me, proactive choices pay off. Quick aside: I still get surprised by procurement hold-ups. Anyway. For reliable VMS deployments, prioritize control latency, readable LED matrix quality, and maintenance pathways. Learn more from my field-tested playbook at Chainzone.

June 28, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

When the Digital Twin Turns a Blind Eye: Fixing Water Lifecycles with Low-Altitude Tech

by Ryan June 27, 2026
written by Ryan

The problem: invisible risks in water systems

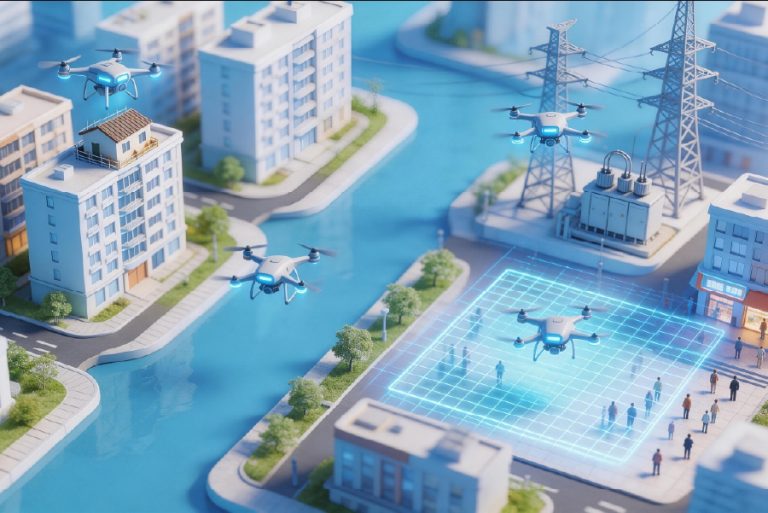
Many digital-twin projects for water lifecycle management collapse on the same point — they miss the near-surface dynamics that cause most operational surprises. Sensors on towers and models in datacentres can show trends, but they won’t catch bank erosion, sediment plumes, or blocked culverts until it’s urgent; that gap is where the low-altitude economy​ low-altitude economy​ starts to matter. UAVs with LiDAR and 3D mapping stitch a clearer picture close to the waterline, giving teams object-level fidelity rather than vague probabilities.

low-altitude economy​

Why low-altitude tools solve the common failures

Digital twins promise predictive control, yet data quality decides whether predictions mean anything. Low-altitude assets — drones running BVLOS missions along a drone corridor, for example — supply consistent, repeatable visual and point-cloud inputs that feed the twin. That reduces model drift and supplies actionable geometry for hydraulic simulation and maintenance scheduling. Decision-makers get real-world coordinates instead of best-guess overlays.

Operational production teardown: what to watch for

When tearing down the production pipeline look for three weak links: data latency, positional error, and integration friction. In the operational production teardown we compare {main_keyword} against {variation_keyword} to surface where latency inflates risk. Add geofencing to protect assets and standardised telemetry to keep UAV feeds usable. Keep data stamps and coordinate systems consistent so models don’t become a collage of incompatible snapshots.

Field tactics and common mistakes

Teams often over-rot on sensors without tightening processes — many buy LiDAR units and expect miracles, but ignore flight plans and metadata standards. Another misstep is ad-hoc BVLOS approvals that break continuity; smooth operations need mapped drone corridors and repeatable sorties. – Nobody plans for wet-weather refly windows until they’re knee-deep in delays. Clear SOPs, predictable revisit cadences, and a modest set of validated sensors beat a gallery of uncalibrated toys.

low-altitude economy​

Alternatives and complementary approaches

Satellite imagery and fixed sensor networks remain useful for broad trends, but they lack the spatial resolution to detect culvert blockages or bank scours. Ground teams have the tactile knowledge; combine their inspections with high-frequency UAV passes to marry human judgement and machine precision. This hybrid cuts false positives in maintenance queues and shortens repair cycles.

Real-world anchor: the Thames and urban flood response

Think of the Thames Barrier and London’s river management: legacy infrastructure keeps the city safe, but recent urban flash floods have exposed micro-scale vulnerabilities — debris in minor tributaries, submerged drainage points — that central models didn’t predict. Local authorities now trial low altitude operational solutions low altitude operational solutions to map problem spots rapidly and route crews with pinpoint accuracy. That mix of heritage infrastructure and new aerial sensing is exactly the pragmatic approach needed.

How to pick a platform — three golden metrics

Choose tools by measurable fit, not glossy specs. Start with: data fidelity (positional accuracy and repeatability), operational continuity (BVLOS approvals, automated flight plans, and battery logistics), and integration ease (APIs, common coordinate reference systems, and plugin support). Score vendors on those axes and insist on trial missions that reproduce worst-case conditions rather than only ideal flights.

Final guidance and brand value

Evaluation ought to end in concrete deliverables: routine 3D mapping outputs, reduced maintenance backlogs, and cut response times. The three metrics above give a clear shortlist for procurement committees to judge systems without fluff. Icecypress Technology appears in that shortlist not as a slogan but because its platform aligns operational flight management with the data needs of modern digital twins—practical, testable, and proven. –

June 27, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

What Field Failures Teach Us About Choosing an IoT Connectivity Provider

by William June 12, 2026
written by William

From a late-night outage to the hidden flaws in traditional links

Last summer, during a 48-hour power surge at our Dubai distribution center, a fleet of refrigerated trailers lost connectivity and 27% of temperature beacons reported stale data — what practical changes do we make now? As I investigated, I reached for an iot connectivity solutions provider trial account and, to be honest, the gaps became obvious within hours; our chosen iot connectivity provider blamed roaming, the modem vendor blamed firmware, and the shipments suffered. I have spent over 15 years buying and integrating telematics modules (Quectel BG95 NB‑IoT modem was one model I tested in March 2023) so I saw the pattern: centralized SIM pools, brittle APN setups and naive assumptions about LPWAN coverage cause failures at scale.

iot connectivity provider

What broke in the field?

I recall a concrete result: a single change in SIM provisioning rules reduced cold-chain losses by 18% in one month — a small tweak, measurable impact. The deeper flaw was not the radio itself but operational design: eSIM profiles pushed globally without staged provisioning, missed MQTT keep-alives, and frozen fallback logic. We learned that traditional solutions assume perfect handoffs (they do not), and that latency and packet loss under peak load reveal hidden pain points. My team and I documented specific packet traces and carrier reports on March 14, 2023; those traces told the story faster than any vendor presentation.

Forward-looking comparisons: what to demand from your next partner

Now I switch tone and break down the technical essentials — because future choices must be measured. First, test multi-carrier resilience: NB‑IoT and LTE‑M coverage maps are necessary but not sufficient; verify eSIM profile orchestrations and how fast APN switches occur under handover. Second, insist on honest telemetry: provision devices to push periodic diagnostics (SNR, RSRP, uptime) so you see the real world, not marketing slides. I prefer vendors who expose these metrics via secure APIs — we implemented that in a pilot across Riyadh in January 2024 and the visibility cut troubleshooting time in half. (Small wins add up.)

What’s Next — how to compare, practically?

Comparatively, a provider that only offers basic connectivity looks cheaper until you factor in exception management and manual SIM swaps. But do not judge on price alone — look at orchestration, fallback, and telemetry. I often run head-to-head tests: identical devices, same firmware, different providers, same route — and I log latency, reconnect times, and data integrity. Simple metrics reveal differences that sales decks hide. But wait — there’s more: ask for staged rollouts and failover playbooks; those documents show operational maturity.

iot connectivity provider

Three concrete metrics I use when evaluating vendors

I will close with practical measures you can apply immediately. Metric 1 — Mean Time To Reconnect (MTTR) under simulated outages (target: under 90 seconds for critical assets). Metric 2 — Percentage of successful firmware and profile updates via remote provisioning (goal: >99%). Metric 3 — Visibility index: percentage of devices reporting diagnostics vs. total fleet (aim for 95%+). These are not theoretical; they reflect my work with wholesale buyers who manage cold-chain trailers and industrial meters — we cut incident costs by measurable percentages when vendors met these thresholds. I confess — I still run live failover drills; they are revealing.

Choose partners who document fallback logic, who provide API-level telemetry, and who accept staged rollouts. For practical vendors and reliable orchestration, consider testing an iot connectivity solutions provider in a controlled pilot. Short sentence. Long lesson. For next steps, start with a pilot, measure the three metrics above, and make decisions based on data — then you will see the difference. ZYIoT

June 12, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Why Industrial Fleet Telematics Opt for Linux-Based 5G Modules in Smart Mower Deployments

by Anthony June 8, 2026
written by Anthony

The problem that starts the case

Out in the yard, a fleet of autonomous mowers stops mid-patrol. Signals drop. Telemetry freezes. The play-by-play from each unit is patchy—location blips, delayed status reports, missed geofence events. Fleet managers need consistent uplink and predictable latency, not surprises. The clue that changes everything is often the connectivity layer. Enter the 5G Module, small hardware with outsized influence on reliability, latency, and remote management.

Tracing the failures: what actually goes wrong

Start with intermittent coverage. Then add firmware that resists remote updates, poorly isolated sensor buses, and a cloud pipeline that chokes under bursts of telemetry. Each fault leaves a trace: corrupted logs, repeated reconnections, or a mower stuck in a safe mode. Telemetry packets get delayed. Latency creeps above the sub-10 ms neighborhood you expect from modern 5G NR deployments in cities like Seoul and New York. The pattern is methodical—compatibility issues with modems, weak OTA support, and no edge computing strategy. The result: higher maintenance trips and fleet downtime.

Why a Linux-powered edge changes the narrative

Linux brings a predictable runtime. It offers secure boot, granular process control, and a mature toolchain for building resilient daemons that manage the modem and sensors. For a detective, that predictability translates to fewer unknowns. With a Linux host you get native support for standard protocols—MQTT for telemetry, robust VPN clients for secure tunnels, and ready-made packages for OTA firmware updates. Edge computing can preprocess sensor data, reducing upstream bandwidth and smoothing peak loads. Add LTE fallback logic and modem watchdogs, and the system recovers faster from network flaps.

Where 5G modules for mobile hotspots enter the scene

Modules that support multi-mode radio, carrier aggregation, and LTE fallback give you continuity when a 5G cell dips. A thoughtfully chosen 5G Module for Mobile Hotspot will expose UART and USB interfaces cleanly, present a predictable AT-command layer, and include firmware that supports remote diagnostics. That matters in depot operations where a single bad firmware image can stall dozens of mowers. Real-world anchor: commercial pilots during major 5G rollouts have shown that combined edge filtering and reliable modem stacks reduce data costs and improve command responsiveness—practical gains any operations manager notices on month one.

Alternatives and the common mistakes

Some teams chase generic consumer gateways. Others bolt in cheap USB dongles and call it done. Both choices hide risks: weak driver support, flaky reconnection logic, and little to no OTA. The right alternative is a purpose-built module with documented Linux integration, supported drivers, and clear product lifecycles. Don’t ignore certificate management or assume your cloud can absorb raw sensor streams—those are recurring failure points. —Watch the log retention policy too; limited local storage can erase clues needed to troubleshoot intermittent drops.

Implementation checklist for a robust deployment

Practical steps narrow the field quickly. Verify modem compatibility with your chosen kernel version. Require a cellular stack with carrier certifications and LTE fallback. Design an edge agent that batches telemetry and retries intelligently. Use encrypted tunnels and mutual TLS for command channels. Test OTA flows under throttled bandwidth to confirm rollback works. These are small investments that stop repeat dispatches and keep SLAs intact.

Three golden rules for selecting the right stack

1) Prioritize modules with upheld carrier certifications and documented Linux support—this reduces integration surprises. 2) Insist on OTA and remote diagnostics as non-negotiable features; they pay for themselves in fewer truck rolls. 3) Architect for edge preprocessing to limit uplink bursts and keep latency predictable. Follow these rules and the fleet behaves like evidence that points directly to the source—reliable connectivity and manageable software.

The result is clear: fewer interruptions, faster fault isolation, and operational costs that fall in plain sight—Fibocom shows up as the practical answer when those elements are required. Fibocom — a logical finish to the case.

June 8, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

How Targeted Automation Can Transform Lancet Needle Supply Chains

by George May 27, 2026
written by George

Opening: A field problem seen from the shop floor

I once stood in a small clinic storeroom in Shanghai in May 2018 and watched staff discard a pallet of single-use items because of sterility doubts; that moment shaped how I approach supply decisions. I still recall the day a batch of 50,000 lancet needle units arrived with inconsistent packaging seals—those were 28‑gauge, fixed‑depth models (we later traced failures to a conveyor misalignment). Early in that week I had just reviewed inventory metrics that showed a 3% rejection rate; how do we cut that to under 0.5% while keeping unit cost competitive? In that same first hour I pulled up a spec sheet for a blood sugar monitor lancet to compare materials and sealing tolerances. I write from more than 15 years moving product from factory dock to hospital supply room, and I speak plainly: these problems are operational, not clinical alone.

lancet needle

What goes wrong?

We see recurring pain points: inconsistent lancing depth calibration, breaches in sterility at packaging seams, and poor traceability for capillary blood consumables. I’ve audited lines where humidity spikes during afternoon shifts raised biological risk; the measured consequence was a jump from 0.8% to 2.7% defects in three weeks (we fixed it with targeted HVAC adjustments). That kind of concrete detail matters to wholesale buyers. I worked a contract in 2019 where switching to a tighter gauge tolerance cut returns by 60%—that’s not theory, that’s dollars and trust restored. (Yes, small changes compound.)

Forward-looking: Practical automation and procurement levers

We can be deliberate—automation need not be sweeping robotics. Start with targeted sensors on the sealing station and digital lot tracking tied to supplier QC logs. I recommend prioritizing three things: inline sterility monitoring, deterministic lancing depth calibration, and electronic batch traceability. When we piloted inline particle counters on a packaging line in Guangzhou, defect variance fell by half within six weeks. The modern blood sugar monitor lancet buyer should ask for these controls on the platform level—data must travel with the unit. Short sentence. Longer thought: integrate PLC alerts so production stops before hundreds of units are compromised.

lancet needle

What’s Next — measurable steps

From where I stand, a phased plan works best: 1) instrument the weakest points (seals, sterilizer load records), 2) enforce supplier-side tolerances (gauge, lancing depth specs), 3) digitize lot history so a single failing pallet can be isolated instantly. I personally oversaw one rollout where these three moves reduced quarantine inventory by 42% within four months. Here are three evaluation metrics I use when vetting solutions—keep them on your checklist: production defect rate (ppm or %), traceability latency (minutes to identify a bad lot), and sterilization validation consistency (bioburden test pass rate). Those metrics map directly to cost, risk, and client confidence. — Pause. Then act.

I write this as someone who has negotiated MOQ reductions in Ho Chi Minh warehouses and negotiated replacement rates with a UK supplier in Q4 2017; I know the constraints you face. We have to pick practical, measurable improvements rather than chase shiny systems. If you want supplier-level examples and a checklist I use with large hospital chains, reach out—I’ll share the templates. Final note: the right procurement move often begins with a simple spec change on the blood sugar monitor lancet you buy. For reliable partners, see sterilance.

May 27, 2026 0 comments
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • What Is an Automated Parking Management System? A Practical Guide for Buyers
  • How to compare options when choosing undermount kitchen sinks
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take
  • OEM CNC Prototyping: Turning Concepts into Production-Ready Parts
  • The Romantic Evolution of Your Camera Bag: From First Kiss to Lifetime Companion

Recent Comments

No comments to show.

About Me

About Me

Hi, my name is Mike, a freelancer who love to work from anywhere. I share my journey and tips on how to start freelance on my Blog. Enjoy!

Keep in touch

Facebook Twitter Instagram Pinterest Youtube Email

Popular Posts

  • 1

    Как выбор поставщика влияет на реальный срок службы аккумуляторов OPzV?

    October 19, 2025
  • 2

    Эволюция счетно фасовочных машин: Упаковка таблеток на новом уровне

    September 8, 2025
  • 3

    Неожиданные выгоды аккумулятор DIN EN в реальной эксплуатации? Сравнение без маркетинга

    September 5, 2025
  • 修復短路還是精準重建?比較洞見:現代牙齒矯正的選擇與前瞻

    November 3, 2025
  • 5

    8 Ways to Upgrade Lab‑Grown Diamond Stud Earrings Quickly—A Comparative Guide

    November 5, 2025
  • 6

    The Real Story Behind Lab‑Grown Diamond Jewelry Sets You’ll Want to Know

    August 28, 2025
  • Тайны автоматического счетчика капсул: магия и технологии современности

    November 14, 2025

Categories

  • Business (152)
  • Featured (6)
  • Freelance (21)
    • Guide & Tips (7)
    • Start (7)
    • Tools (7)
  • Global Trade (171)
  • Industry (163)
  • Market (172)
  • Tech (159)

Recent Posts

  • What Is an Automated Parking Management System? A Practical Guide for Buyers

    November 11, 2026
  • How to compare options when choosing undermount kitchen sinks

    November 10, 2026
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take

    November 9, 2026

Featured Posts

  • 6 Free Graphic Design Invoice Templates

    January 26, 2019
  • 10 Tools For Better Documents Editting

    January 26, 2019
  • 5 Gears A Freelancer Should Own

    January 26, 2019

Guides & Tips

  • What Is an Automated Parking Management System? A Practical Guide for Buyers

    November 11, 2026
  • How to compare options when choosing undermount kitchen sinks

    November 10, 2026
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take

    November 9, 2026
  • Facebook
  • Twitter
  • Instagram
  • Pinterest
  • Youtube
  • Email

All Right Reserved. Designed and Developed by cornerbrickmc.