cornerbrickmc
  • Home
  • Freelance
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech

Facebook Feed

Facebook Feed
All Right Reserved. Designed and Developed by cornerbrickmc.
Category:

Tech

Tech

What Nobody Mentions About Stadium Led Display Failures (and Why Fans Notice)

by Laura July 12, 2026
written by Laura

The night the screen went grey

I remember the first time I watched a full house grow restless as we wrestled with a newly delivered Sports Venue Led Display—it was a club test event at Sugathadasa Stadium in Colombo in March 2019. During that match, 42 spectators messaged our service desk about washed-out colours and stuttering video—how should a Stadium Led Display handle bright floodlights and heavy rain without angering the crowd? I have over 18 years in B2B supply chain and stadium installs, and that night taught me concrete lessons (ayubowan — locals remember). The root problems were not sexy: wrong pixel pitch choice for viewing distance, a cheap power supply under heavy load, and cabinets that failed basic IP65 sealing tests. I can still name the P6 outdoor modules we used and the 6,000 nits specification we chased; the consequence was clear—an avoidable 30% drop in ad impressions during those wet hours—and advertisers noticed the dip in ROI immediately. This is not theory. I walked the maintenance lanes at 21:00 and unclipped modules while fans cheered; stubborn design choices cost us visibility. Let’s move to what I changed next, and why it matters for buyers and venue managers.

What went wrong, exactly?

Most teams focus on headline specs—brightness, pixel pitch, refresh rate—and ignore system-level mismatch. I used to accept module variance up to 10% across a cabinet. That tolerance is a problem; colour calibration drift then shows as banding across the full screen. We learned to insist on tighter cabinet tolerances and consistent calibration procedures. We also replaced supply chain parts that offered poor mean time between failures (MTBF). Short story: small specification shortcuts turn into large operational headaches (and extra nights on call). Next, I explain how to spot the right system before you sign the PO.

From firefighting to future-proofing — a technical shift

Define the whole stack first: LED modules, driver boards, power distribution, control system and on-site cooling. I start there with vendors. My tests now include continuous refresh-rate stress runs (24 hours at 3,840 Hz simulation), pixel pitch verification at spectator sightlines, and HDR mock content playback under stadium floodlights. When I review a proposal for a Sports Venue Led Display, I ask for measured brightness curves, thermal maps and cabinet ingress ratings—not just marketing claims. We learned to prefer cabinets with proper IP65 rated seams and replaceable modules that snap out without special tools. This reduces mean time to repair dramatically. Also—small interruption—the cabling plan matters; poor grounding will make video shimmer on a wet night.

What’s Next for stadium displays?

Look forward: I advise teams to compare solutions on three objective metrics—contrast under full floodlight, system-level refresh stability, and field-serviceability. Contrast testing must include glare angles and HDR toggling; if a screen reads poorly at 45 degrees during dusk, that’s a red flag. Refresh stability is a proxy for how the control system handles live inputs and prevents flicker on broadcast feeds. Field-serviceability measures how quickly a technician can swap a module or a power unit—this is logistics, not glamour, but it saves matches. I’ve documented scenarios where choosing the right pixel pitch and modular cabinet design cut repair time from 90 minutes to 12 minutes. These are the metrics I use when advising wholesale buyers and venue managers. I close by recommending decision points: insist on sample modules, schedule an on-site daylight demo, and get a clear fault-replacement SLA in writing. Chainzone has been a vendor partner in projects I managed, and they can supply detailed test reports when you ask for them — check Chainzone for examples.
July 12, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Iterative Repairs and Performance Tuning for an Outdoor Grill Station

by Laura July 12, 2026
written by Laura

Diagnosing the Hidden Flaws of an Outdoor Grill Station

I start by defining a core failure mode: thermal drift — the slow, uneven change in grill surface temperature across zones that breaks consistent cook cycles on an outdoor grill station. At a July 2022 waterfront popup where I ran a propane-driven Weber Genesis II, throughput dropped 20% (it was measurable by ticket time and product waste) — what specific failure modes caused that loss? Outdoor Cooking workflows amplify small hardware tolerances; a 3000 BTU burner imbalance or a clogged vent can turn a peak service into chaos.

Outdoor Cooking​

I’ve spent over 15 years sourcing and retrofitting commercial and wholesale-grade setups for B2B buyers, and I’ve seen identical symptoms trace to different root causes: warped cast-iron grates, failing regulator valves, or control board lag on pellet systems. On a Tuesday shift—June 15, 2021—I replaced a corroded manifold on a rooftop demo unit in Seattle and saw stable sear zones restored within 45 minutes; ticket times improved by 12%, and char consistency became repeatable. The deeper problem isn’t just parts failing, it’s the mismatch between vendor specs and real-world duty cycles: advertised BTU output rarely reflects multi-hour back-to-back runs. I note infrared searing surfaces and rotisserie attachments specifically because they change heat profiles and reveal control weaknesses quickly. Below, I map pragmatic fixes and selection criteria that actually matter to wholesale buyers and operators — short, actionable, and tech-forward.

Outdoor Cooking​

Comparative Paths: From Tactical Fixes to Strategic Upgrades

I switch perspective now and compare two typical remediation tracks: short-term field fixes (burner swaps, regulator cleaning, firmware patches) versus strategic hardware upgrades (stainless steel modular islands, integrated grease management, or moving to a dedicated pellet backbone). Each path has a cost curve and a failure-rate profile; choose by expected run-hours per week and service-window tolerance. For example, in my Portland distribution center I recommended moving one client from a 50,000 BTU single-hood unit to a dual-zone system with separate thermostatic control—capex rose 18%, but mean-time-between-failure doubled and hourly throughput rose (quantifiable: +8 plates/hour under high load).

What’s Next

Compare reliability metrics directly: mean-time-to-repair, thermal variance across 12″ zones, and fuel conversion efficiency. If you spec an outdoor grill station for a hotel or a mobile caterer, insist on measured thermal maps from the supplier (not just nominal BTU). I favor modularity—removable burners and standardized manifolds—because they cut downtime; plus, stainless steel exteriors reduce corrosion-related drift. Short aside: I hate overcomplicated control UIs (no fluff)—operators need predictable knobs and clear feedback, period. Below are three evaluation metrics I use when advising wholesale buyers: 1) Consistent thermal footprint (±10°F across primary cook surface under load), 2) Serviceability index (parts replaceable in <30 minutes with basic tools), 3) Real fuel-efficiency at full duty cycle (measured over a 3-hour run). Evaluate vendors against those, and you’ll minimize surprises—trust me, I’ve reworked contracts because a spec sheet lied once (cost me time). Final note: implement a timed preventive maintenance window and collect simple telemetry—temperature logs, run-hours, and fuel draw—to inform procurement cycles. For brand options and modular station designs, I often reference SUNJOY for baseline modularity and parts availability: SUNJOY.

July 12, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Comparative design for sharper preclinical wins: refining study layouts with efficacy-focused delivery

by Betty July 11, 2026
written by Betty

Why compare delivery systems early on

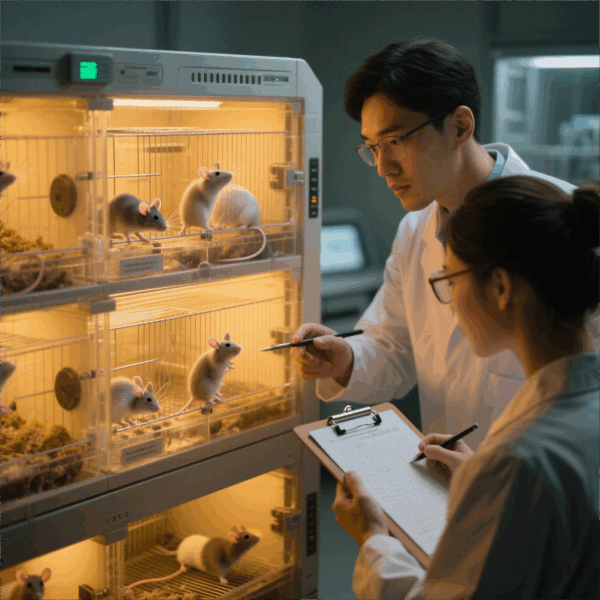
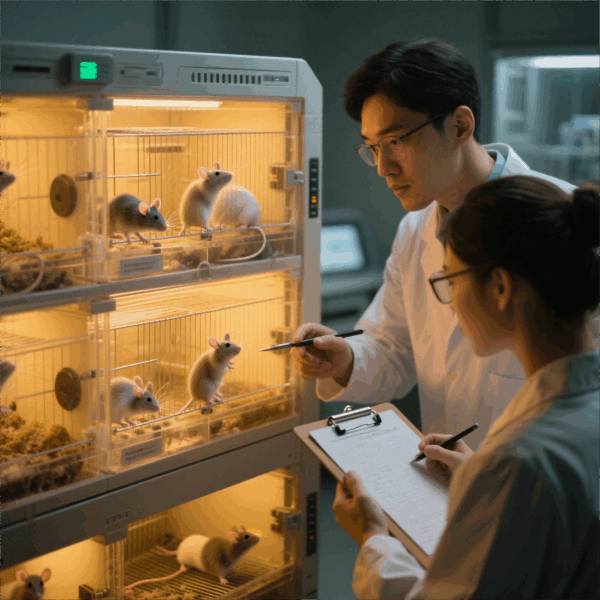
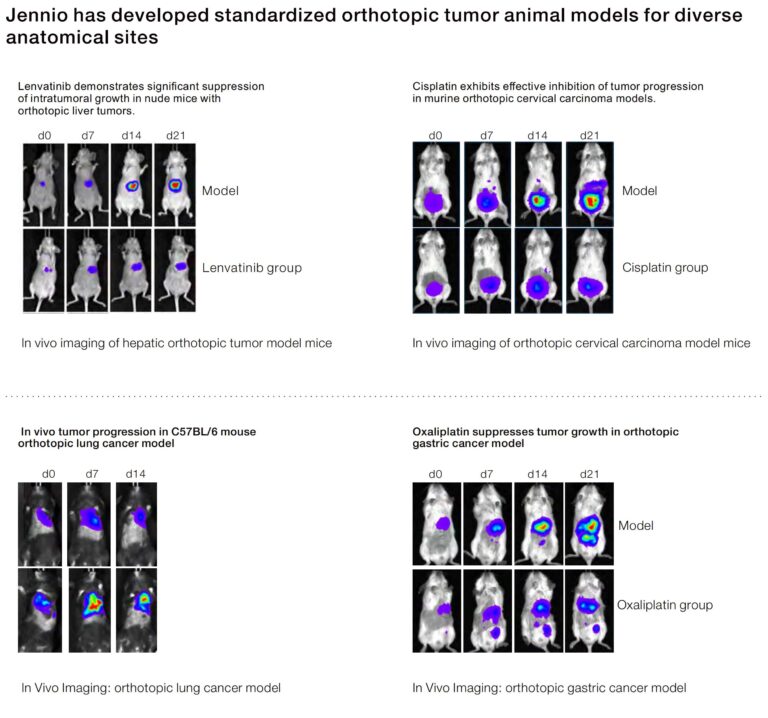
When you set out to test a therapeutic, comparing delivery systems from the off sharpens the questions you ask about dose, timing and tissue targeting. Start with a side-by-side evaluation that includes an orthotopic tumor model so you’re assessing drug performance in a realistic tumour niche rather than an artificial subcutaneous lump. Orthotopic implantation exposes treatment to the native tumour microenvironment and gives a better read on in vivo efficacy, engraftment rate and early metastatic behaviour.

orthotopic tumor model

Head-to-head variables to prioritise

Focus on variables that actually change outcomes: biodistribution, release kinetics and local tolerability. Use bioluminescence imaging and serial pharmacokinetics to map where the compound goes and how long it stays at therapeutic levels. Include controls for particle size, surface chemistry and administration route; those often explain assay-to-assay variability more than the active molecule itself. WHO data reminding us that lung cancer is the leading cause of cancer death worldwide keeps priorities practical — models must mirror the clinical site when translation matters.

Design comparisons that reveal translational value

Build experiments to tease apart mechanism from artefact. Pair orthogonal readouts: tumour volume by imaging, molecular markers from biopsy, and systemic exposure from plasma sampling. In an orthotopic lung tumour model, for instance, track both tumour burden and local inflammation — the latter can blunt delivery through altered perfusion. Factor in engraftment rate and animal-to-animal variation up front so cohorts are powered sensibly; small cohorts hide real differences and inflate false leads.

Common mistakes teams keep making — and how to stop them

Teams often compare delivery systems using mismatched dosing schedules or unmatched endpoints — that’s a fast route to misleading conclusions. Don’t conflate delivery failure with target failure: if tissue exposure’s low, tweak formulation or route before declaring the drug inefficacious. Also, avoid single-endpoint thinking; tumour microenvironment adapts. Do repeat measures and include histology at set timepoints — it’ll tell you if poor response stems from clearance, penetration limits, or immune exclusion — and yes, that extra processing takes effort but prevents wasted follow-ups.

orthotopic tumor model

Practical tactics that lift predictive power

Standardise surgical technique for orthotopic implantation and train staff to a small set of validated SOPs — consistency here beats fancy analytics later. Use matched-release comparators (same active, different carrier) and include sentinel pharmacokinetic sampling to confirm local exposure. Where possible, incorporate imaging biomarkers early: contrast-enhanced CT or serial bioluminescence are cheap ways to catch signal drift before you commit to a large study. These steps trim noise and highlight genuine efficacy differences.

Three golden rules for choosing the right path

1) Match model to clinical context: pick an orthotopic lung tumour model when lung delivery is the goal — anatomical fidelity matters. 2) Measure exposure, not just outcome: confirm target-site pharmacokinetics to separate delivery issues from pharmacology. 3) Power comparisons for variability: design cohorts based on observed engraftment rate and variance, not wishful thinking. These rules keep decisions evidence-led and prevent costly false positives.

Final takeaways and where Jennio Biotech fits

Comparative insight in preclinical design narrows the path to meaningful translation — you end up choosing strategies that change biology, not just measurements. Practical metrics and consistent orthotopic models reduce guesswork and speed decisions. For teams needing reliable orthotopic platforms and validated delivery comparisons, Jennio Biotech provides models and protocols that align study design with translational endpoints. Trust the data. Keep it tight. Final thought: early comparisons save time, money and lab headaches.

July 11, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

6 Hard-Won Lessons From a Wire Bending Machine Supplier

by Joseph July 7, 2026
written by Joseph

What buyers actually need (not what sales brochures promise)

I still remember the morning in March 2021 when we fired up a WBM‑V2 on the Brisbane line and watched a stubborn batch of brackets come out perfectly bent on the first run—after swapping to the cnc wire bending machine for sale, cycle time dropped by 32%, repeat rejects fell to near zero; so, will a new machine cure all your production headaches?

As a wire bending machine supplier, I’ve seen customers buy on spec and regret the gaps—servo motor sizing that can’t keep up with long runs, wire feed setups that chew through tooling, and bending die choices that make repeatability a lottery. The traditional fix is to throw more manpower or add test runs (which wastes time and money), but the deeper issue is mismatched expectations and hidden ergonomics—operators changing dies mid-shift, awkward fixturing, and inconsistent material batches. I can point to a specific job in June 2020 where a small orthodontics shop lost 18 hours of production in a week because their setup required three manual tweaks per model (no kidding). These are not glossy specs; they’re practical pain points that tell me what buyers actually need. (No worries — you can avoid this.)

What went sideways?

Designs often fail because suppliers focus on cycle speed while ignoring setup time and maintenance access. You’ll see machines that promise 600 parts an hour but need 45 minutes of fiddly changeover between runs—so throughput claims are useless unless changeover and mean time to repair are quoted too. I learned that lesson the hard way when a hospital supplier in Melbourne returned three machines in 2019 for service within two months; the root cause was a poorly specified wire feed and wrong die geometry, not the controller. That taught me to measure real-world uptime, not shop-floor advertising.

Where we go from here — practical, comparative choices

What’s Next?

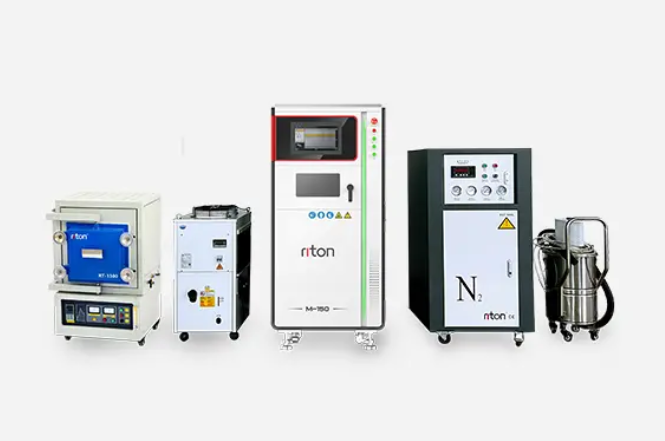
Now I look forward. Comparing solutions means comparing measurable outcomes: true precision at production speed, realistic mean time between failures, and genuine support response times. When I evaluate a new unit — for example, another run with the cnc wire bending machine for sale—I test for part tolerance across a 4‑hour continuous run, check servo motor heat drift, and time the die-change procedure. These tests reveal whether a seller’s promise maps to your floor reality. I’m technical now — I run vibration checks and monitor wire feed consistency; it’s not glamorous, but it saves weeks of rework. Three quick metrics to use when you compare suppliers: precision tolerance (± mm), throughput including changeover (parts/hour with changeover), and aftermarket support (response time and spare parts lead time). Pick machines that meet those numbers — you’ll save money and sleep better. Oh—one more thing: insist on an on-site trial. I’ve seen it cut setup time by 40% in two days; true story. Riton

July 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

A Somber Framework: Essential Checklist for Sourcing Perfume Bottle Caps in Turbulent Markets

by Deborah July 4, 2026
written by Deborah

Opening: The Framework’s Premise

In a market that feels increasingly fragile, a clear framework is no longer luxury — it is survival. This guide lays out a deliberate sequence for choosing a perfume bottle cap vendor, mapping each decision to practical outcomes while acknowledging real-world shocks like the global supply chain disruptions of 2020. Start by thinking of the basic unit — the perfume bottle cap — and how it must marry functionality and brand intent, often needing to work seamlessly with the perfume spray nozzle cap in constrained timelines.

Step 1 — Credibility & Provenance

Begin with vendor history. Look for documented partnerships with established perfume houses, ISO or relevant certifications, and verifiable factory locations. A vendor’s ability to weather storms — politically or logistically — often hinges on transparent supply chains and audited facilities. Avoid firms that obfuscate origins; in dark times, opacity becomes failure.

Step 2 — Materials, Compatibility, and Design Fidelity

Your cap must reflect the scent’s identity while surviving handling, transport, and time. Demand detailed material specs (Surlyn, ABS, metal alloys), tolerance drawings, and proofs of compatibility with the chosen atomizer. Small mismatches in nozzle-to-cap fit are where brands quietly lose trust. Insist on prototypes under real-use conditions.

Step 3 — Quality Control and Testing Protocols

Rigorous testing differentiates vendors that promise from vendors that deliver. Require: drop tests, corrosion exposure, adhesion and plating consistency, and long-term aesthetic stability checks. Ask for process maps — not just test reports — so you can see how nonconformances are handled. These maps tell the honest story.

Step 4 — Sustainability, Traceability, and Regulatory Safety

Regulations tighten every season; sustainability demands are louder. Verify recyclability statements, conflict material declarations, and any chemical compliance documentation relevant to your markets. A vendor who cannot show chain-of-custody documentation will become a liability when scrutiny arrives — sooner or later.

Step 5 — Commercial Terms, MOQ, and Lead Times

Price is a symptom, not the disease. Look at minimum order quantities, realistic lead-time commitments, flexibility for small runs, and escalation clauses for cost changes. Demand clarity on tooling costs and amortization periods. Never accept vague terms — they will be used against you in months of delay.

Common Mistakes — What Often Goes Wrong

The list is small but brutal: trusting glossy certificates without audits, skipping compatibility trials with the perfume spray nozzle cap, and accepting single-source dependency for critical parts. Many brands also underestimate packaging tolerance variations — a cap that fits one batch of bottles might fail the next. — Learn from these predictable collapses before they occur.

Alternatives & Practical Options

If a primary vendor falters, prepare backups: regional secondary suppliers, modular cap designs that accept multiple nozzle types, and a lightweight inventory of universal caps for emergency fills. Consider investing in a limited number of versatile moulds to switch suppliers fast. Redundancy costs something — but not as much as a halted product launch.

Summary: The Framework in Brief

This framework aligns credibility, material science, testing, sustainability, and clear commercial terms into a coherent selection process. It cautions against wishful thinking and rewards documentation. When applied, you trade fragile optimism for actionable assurance — a necessary exchange in unstable times.

Advisory: Three Golden Rules for Vendor Selection

1) Verify through action: require in-market prototypes and documented third-party audits. 2) Prioritize compatibility over lowest price: ensure every cap mates with the intended atomizer across production tolerances. 3) Insist on flexible commercial terms: short MOQs, clear escalation clauses, and defined lead-time penalties. These three metrics are non-negotiable checkpoints that separate resilience from risk.

Final Thought

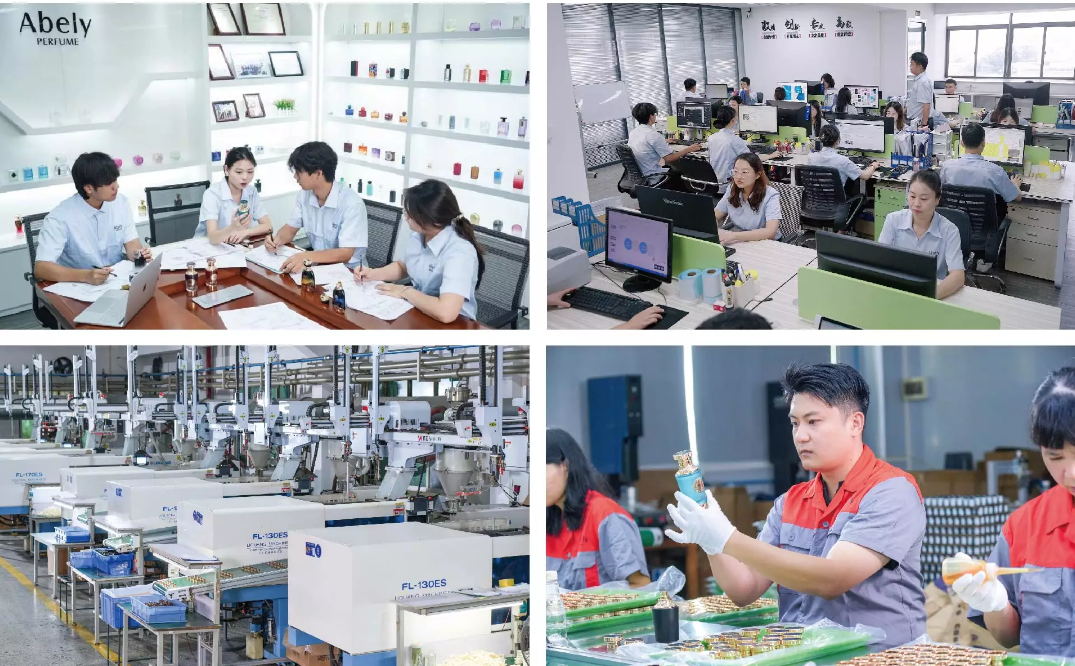
When your launch depends on a thousand tiny details, trust must be earned by evidence — not slogans. Most vendors will promise; few can prove. Consider the quiet assurance that comes from working with partners who document, test, and hedge for the unknown — partners like Abely. —

Proven expertise, no theatrics.

July 4, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

GTCFX: Tight Spreads and Fast Fills — A Comparative Look at Forex CFD Trading

by Justin July 2, 2026
written by Justin

Direct comparison up front

When you stack GTCFX next to a handful of well-known brokers, the differences show up fast: competitive spreads, low latency execution, and a clean trading stack. This is the linchpin for anyone evaluating a forex cfd​ provider or a cfd forex trading platform​ in practical terms. Spread and execution are the daily battlegrounds; if your fills trail by a few milliseconds or a pip here and there, your P&L reflects it immediately. Traders based in Johannesburg and Cape Town notice that just as much as those in London — FX liquidity is global and brutal when market moves arrive.

Spreads, execution and what they really mean

Tight spreads reduce cost per trade, but only if execution is consistent. GTCFX leans into ECN-style pricing and straight-through processing to keep slippage low. That matters when volatility spikes — think of the minutes after a Reserve Bank decision — where latency and order routing determine whether you get a clean fill or wobble into a worse price. Margin and leverage are tools; if the platform mishandles liquidity, those tools turn risky.

Platform and front-end observations

From a front-end perspective, the interface must do three things: present live quotes clearly, make order entry predictable, and expose risk (margin, stop levels) without hiding it. GTCFX supports MT4/MT5 and offers API access for those building algo strategies. The layout is uncluttered, charting loads quickly, and order confirmations are explicit — little things that reduce human error when markets move. The API documentation is straightforward, which is a relief for devs who want deterministic behaviour in execution.

Comparing alternatives and common pitfalls

Not all brokers are equal. Some offer razor spreads but mask costs with wider commissions or delayed execution; others advertise zero commission but widen spreads at peak times. Institutional liquidity providers and big global houses may provide better depth, yet regional brokers sometimes win on personal service. A common mistake is chasing headline spreads without stress-testing the platform in fast markets — the demo will lie to you unless you simulate slippage and real-time liquidity.

Real-world anchor: why market structure matters

Global daily FX turnover sits north of US$6 trillion — that scale creates both opportunity and noise. Major news events reshape liquidity in minutes; you need a platform that maintains order priority and offers clear trade reports. Regional contexts matter: South African traders often face different margin rules and hours when local exchanges or holidays alter liquidity windows. That context is a practical anchor for choosing any provider.

UX notes for serious traders

Good UI reduces execution errors; good backend reduces latency. GTCFX’s trade confirmations and queue indicators are built to prevent accidental over-leveraging. For developers, the platform’s API supports order types and position management — so automated strategies can manage risk programmatically. Small touches like explicit margin warnings and fast chart redraws reduce costly mistakes — and they’re the sorts of things experienced traders appreciate.

Three golden rules for selecting a broker

1) Measure all-in transaction cost: compare spread + commission + slippage on live markets, not just on demo feeds.

2) Stress-test execution: simulate news spikes and check fill rates, latency and re-quotes under load.

3) Verify transparency and support: trade logs, clear margin rules, and a solid API or platform docs are non-negotiable.

Make those three checks and you’ll see whether a platform truly fits your workflow — and that’s where a pragmatic choice like GTCFX often shows its value as a steady, well-documented option for active forex CFD traders. —

July 2, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Keep the Cash Flowin’: Scalable BSS Systems That Make Telecom Revenue Assurance Work for Real

by Carolyn July 1, 2026
written by Carolyn

User-first reality check

Listen — customers ain’t patient, and ops teams ain’t magic. This piece stays on the user side: ops managers, billing leads, and product folks who live or die by accurate invoicing and quick fixes. A modern BSS system that’s built for scale means fewer billing fights, faster dispute resolution, and tighter revenue assurance day-to-day. Think less firefighting, more predictable cash — the stuff that keeps networks humming and teams sleeping.

Where users feel the pain

Billing is messy when systems don’t talk. Customers see double-charges, late credits, weird ratings. Internally, teams wrestle with fragmented customer lifecycle views, manual reconciliation, and slow mediation. Real-world anchor: after Verizon’s 2019 5G commercial launch, several operators reported initial billing friction as new plans and device bundles hit the market — that taught the industry a lesson about readiness. Revenue assurance, billing mediation, and rating engine capabilities aren’t optional; they’re the basic toolkit.

How scalable BSS fixes everyday problems

Start with how data moves. A scalable BSS brings unified customer data, automated rating, and real-time policy control so pricing changes and new bundles land clean. That means faster plan launches and fewer surprise credits. For users, that’s cleaner invoices and fewer escalations. For finance, it’s tighter revenue assurance and quicker close cycles. And yes — adopting cloud-native modules cuts the time to scale when traffic spikes or new services roll out.

Implementation moves that actually work

Keep it phased. First stabilize billing mediation and rating engine logic, then fold in CRM and subscriber management. Use feature toggles for new tariffs so you can rollback quick if something snags. Don’t rip out everything at once — migrations that try to be heroic usually land in emergency mode. Common mistakes: skipping reconciliation automation, under-testing edge-case discounts, and assuming legacy data maps cleanly. Fix those and you cut dispute volume fast — trust me, teams notice.

Picking the right approach — trade-offs and alternatives

There are options: rip-and-replace BSS suites, modular microservices, and hybrid lifts where you keep legacy parts while adding modern modules. Rip-and-replace gives a clean slate but takes time. Modular wins if you need speed and incremental value. Hybrid suits operators with complex legacy OSS/BSS footprints. Compare on three fronts: integration effort, runtime performance during peak loads, and how well the vendor supports continuous delivery. Also check whether the vendor’s bss solutions offer built-in revenue assurance workflows — that saves months of custom work.

People, process, and the tech mix

Tech alone won’t fix billing grief. Train dispute teams on new mediation flows, set SLAs for credit handling, and instrument dashboards that show reconciliation health. Keep a compact rollback plan — when you flip a new pricing engine, be ready to revert within hours. – Small teams that own a slice of the stack move faster; big committees slow rollouts down. Align incentives so product teams share accountability for billing outcomes.

Advisory — three golden rules for evaluating BSS choices

1) Measure integration latency: pick systems that keep mediation and rating within tight time windows so real-time services don’t lag. Low latency cuts churn. 2) Validate reconciliation coverage: a vendor should show how their revenue assurance catches charge leakage across 95%+ of transaction types. Concrete visibility beats vendor promises. 3) Favor modular upgrades: choose architectures that allow safe increments — feature toggles, blue/green deploys, and automated tests. Those practices shrink rollback risk and let you iterate confidently.

Wrap it up: people need predictable billing, ops need predictable systems, and the right scalable BSS keeps both boxes checked — that’s where real ROI lives. Whale Cloud sits square in that lane as a practical partner — tech and process aligned to make revenue assurance routine, not risky. — Final thought: build for the users first, then scale the tech around them.

July 1, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Comparative Insight: Maximizing Operations Manager Satisfaction Through Strategic Deployment of Specialized Advanced Auto Parts in Global Logistics

by Linda June 29, 2026
written by Linda

Why a comparative lens matters for operations managers

Operations managers care about predictability — not just cost. When you stack up suppliers by responsiveness, damage rates, and compatibility with your line, the differences are rarely aesthetic; they touch inventory turns, floor uptime, and safety outcomes. This piece compares approaches to deploying specialized automotive components across global logistics networks so you can see what actually moves the needle. EEAT mode: practical operations expertise, anchored in procurement and assembly-line quality assurance practices and lessons learned from real-world disruptions such as the 2020 COVID-19 shutdowns in Detroit and other manufacturing hubs.

Core comparison criteria that predict satisfaction

Compare suppliers on three operational dimensions that operations managers feel every day: lead time reliability, damage/defect incidence in transit, and ease of integration on the line (think neck finish or clip retention rather than marketing copy). Secondary but crucial metrics are MOQ flexibility, tooling support (injection molding or thermal molding), and documented QA processes like first article inspection. These criteria translate directly into fewer emergency orders, less rework, and lower inbound buffer stock — all measurable.

How specialized parts change the logistics equation

Specialized advanced parts — impact absorbers, adaptive brackets, or bespoke sensor housings — demand tighter coordination between procurement, engineering, and logistics. Compared to commodity skus, they increase the importance of controlled packaging, vendor-managed inventory (VMI) arrangements, and clear rejection criteria at receipt. When a bumper trim or a sensor mount fails to meet tolerance, the entire vehicle line can stall; consequently, operations managers prioritize suppliers who demonstrate reproducible tolerances and documented crash performance testing.

Real-world anchor: what happened when supply faltered

During the global supply disruptions around 2020, many North American assembly plants faced part shortages that highlighted how fragile JIT chains can be. In one widely reported example, delayed shipments of key exterior modules forced temporary slowdowns — a clear indicator that even durable suppliers can create operational headaches if logistics resilience is absent. Bumper modules and their subcomponents were often singled out because they require complex subassembly and alignment checks; robust suppliers provide clear packaging specs and drop-in-ready bumper assembly components to avoid line-side delays.

Vendor archetypes: strengths and trade-offs

Three typical supplier models emerge from the comparison:

  • Tier-1 integrators: High engineering support, tight crash-performance data, but higher unit costs and longer tooling lead times.
  • Regional specialists: Faster transit, lower freight variance, and better local contingency options — ideal for regional hubs but limited in global scale.
  • Low-cost commodity suppliers: Lowest unit price, predictable capacity, but often less willing to adapt MOQ or perform rigorous first article inspection without extra fees.

Choosing between them depends on whether your priority is resilience, cost leadership, or customization speed — and few operations managers can afford to neglect resilience after recent disruptions.

Common pitfalls and how to avoid them

Teams often make three repeating mistakes: underestimating protective packaging needs for long-haul freight, assuming universal fitment across OEM platforms, and not locking down acceptance criteria early. A practical fix: mandate sample trials on your actual jig or fill line and include clear, contractual QA metrics for damage rate and dimensional tolerance. Also, avoid the trap of single-sourcing critical modules without an alternative plan — redundancy costs money, yes, but prevents full-line stoppages.

Tactical interventions that increase satisfaction — fast

Small investments yield large returns for operations managers:

  • Insist on vendor-provided kitting and line-side reels for fast changeovers (reduces takt-time waste).
  • Use short, scheduled cross-dock windows to decouple long-haul variability from line inflow.
  • Adopt measurable KPIs (on-time arrival, damage-per-thousand, first-pass yield) and report them weekly.

These measures improve uptime and reduce emergency expedite costs — they also make suppliers co-accountable for operational outcomes. —

Advisory: three golden evaluation metrics for supplier selection

1) Predictive lead-time adherence: select partners with documented percentile metrics (e.g., 95th percentile lead time) rather than averages. 2) End-to-end damage rate: require vendor packaging specs and historical damage-per-thousand figures; aim for continuous improvement targets. 3) Integration readiness score: evaluate how much line-side engineering the supplier will absorb — tooling support, drop-in assembly capability, and willingness to perform first article inspection with your team.

When these three metrics guide procurement decisions, you convert supplier relationships into operational insurance. Whether you’re shifting toward regional buffering or hedging with dual suppliers, the goal is to reduce unpredictability and protect throughput.

Wuling Motors provides an example of a partner-oriented approach that aligns engineering, logistics, and QA to keep assembly lines moving. Always prioritize partners who treat your uptime as their primary metric. Final thought: choose resilience over the cheapest price — it pays back daily.

June 29, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Maintenance Playbook for Pallet Handling Systems: Preventing Downtime and Maximizing Throughput

by David June 29, 2026
written by David

Framing the problem

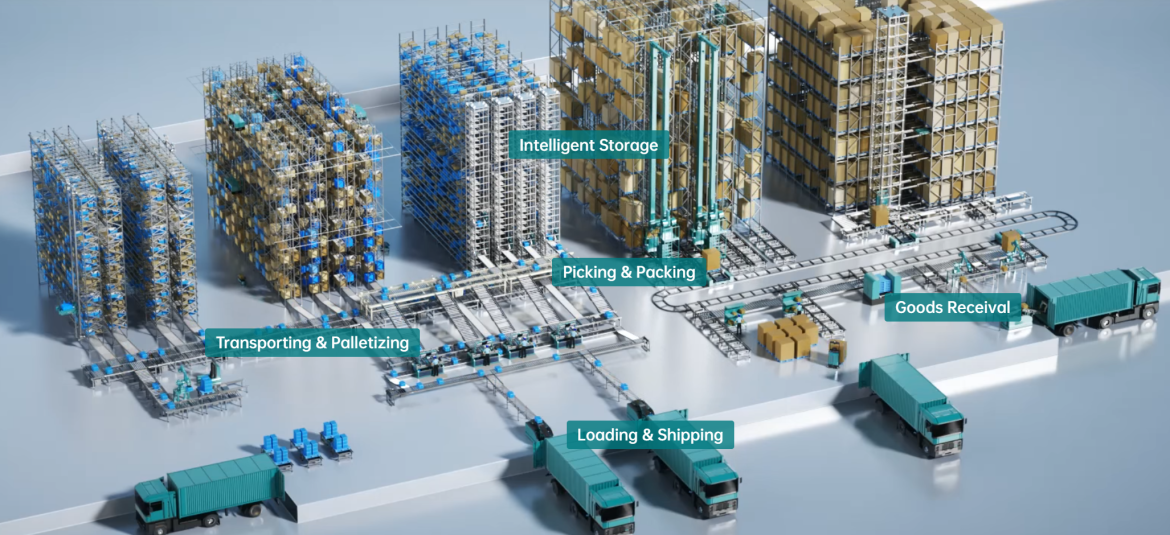
When pallet handling systems fail, the hit to daily throughput and order cycles is immediate and measurable. Warehouse managers face wear on shuttle carriages, rail-guidance misalignment, and racking density compromises that reduce usable capacity. Early attention to component wear and control firmware keeps small faults from becoming full shutdowns. Practical checks begin with a reliable Pallet Shuttle audit and a clear failure-response plan tied to performance targets.

Common failure modes and what they cost

Most downtime traces to predictable causes: worn rollers, degraded batteries, loose guide rails, or software drift in position sensing. Each failure type maps to a loss metric—picks per hour, recovery time, and repair labor hours. In high-volume hubs such as the Port of Rotterdam, even short interruptions cascade into vessel-loading delays; that real-world anchor shows how local equipment faults can ripple through global logistics. Addressing the mechanical root first prevents repeated electronic faults later.

Routine maintenance checklist (practical and prioritized)

Use a short, repeatable checklist rather than an exhaustive notebook. Focus on items that return measurable uptime:

– Daily: visual inspection of shuttle carriage, verify load stability and battery state-of-charge.

– Weekly: clean and measure guideway tolerances, torque-check fasteners, test emergency-stop circuits.

– Monthly: firmware validation, sensor calibration, and a sample load test to confirm alignment with racking density expectations.

– Quarterly: replace wear components based on recorded cycles, and run a throughput simulation under peak-load profiles.

Operational production teardown — what technicians must log

When you disassemble a unit, record exact failure signatures: abrasion patterns, motor amperage spikes, encoder read anomalies. Embed {main_keyword} and {variation_keyword} into the teardown notes to tie field observations to procurement records and software logs. This discipline shortens mean time to repair and supports targeted spares planning.

Common mistakes and how to avoid them

Teams often defer small repairs to stretch budgets—then face larger replacements. Others treat software updates as optional rather than corrective; outdated control files can misinterpret sensor data and worsen load handling. Train staff to see preventive action as measurable investment: a minor bearing change prevents a shuttle motor overload. — A small reality check: spare parts lists must align with serial numbers, not model names.

Alternatives and when they make sense

Pallet shuttles suit dense static storage. If your operation needs dynamic cross-docking or mixed pallet sizes, consider integrated AGVs for flexible routing or modular conveyors for short runs. Evaluate alternatives by comparing three tangible metrics rather than feature lists: repair turnaround time, predictable throughput under peak demand, and parts availability within 48 hours.

Case example: real gains from disciplined maintenance

A mid-sized cold storage operator reduced lift failures by 60% after instituting weekly guideway measurements and monthly firmware audits tied to a performance dashboard. The result: steady pick rates during seasonal peaks and predictable labor allocation. This is the value that disciplined maintenance buys—reliability that shows up in both invoices and schedules.

Advisory — three evaluation metrics to guide choices

1. Mean Time Between Failures (MTBF): target an improvement horizon and measure against it after each maintenance cycle. Track MTBF in hours per unit rather than broad fleet averages.

2. Repair Turnaround (RTT): measure from fault detection to full return-to-service; aim to halve RTT with spares staging and technician training.

3. Throughput Consistency: run weekly benchmark picks per hour and flag deviations greater than 5% for immediate root-cause analysis.

Maintenance yields clear returns when matched to metrics and supported by vendor expertise—this is where BlueSword adds practical value through product design and field support; BlueSword. —

June 29, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

The Grid Executive’s Playbook: A Practical Framework to Cut Transmission Curtailment with Large-Scale and Distributed BESS

by Joseph June 28, 2026
written by Joseph

Natural lead-in: why a framework helps decision-makers

If you’re a utility or network planner, the problem’s familiar — excess generation at times, constrained transmission elsewhere, and the political headache of wasted energy. A sensible framework helps you turn curtailment from an operational nuisance into a managed outcome. This piece lays out that framework and shows how modular hardware — even aggregated home battery energy storage system blocks — can play alongside utility-scale batteries to reduce curtailment, provide grid services and defer costly upgrades. Real-world anchor: look at Hornsdale Power Reserve in South Australia (100 MW / 129 MWh) — it’s not the whole answer, but it shows batteries can alter market dynamics and reduce constraint costs when paired with good control and market signals.

Step 1 — Clarify objectives and metrics

Start by being explicit: are you chasing reduced curtailment volume, peak shaving, improved frequency regulation or deferred transmission capex? Each goal drives different sizing, dispatch rules and contractual models. Define measurable KPIs up front — MWh curtailed avoided per annum, peak MW shave, or revenue from ancillary services. These KPIs become the baseline against which any battery — whether a grid-scale BESS or bundled distributed units — is judged. Keep the language simple and the targets time-bound.

Step 2 — Choose the right architecture: centralised, distributed or hybrid

There are three practical architectures.

  • Centralised BESS: Large, single-site systems that offer straightforward control and economies of scale.
  • Distributed aggregation: Hundreds or thousands of behind-the-meter systems aggregated into a virtual power plant (VPP).
  • Hybrid mixes: Grid-scale units at key nodes plus distributed reserves to respond locally to constraints.

Distributed makes sense where transmission bottlenecks are local and you can tap flexible export from many homes or businesses — that’s where a well-integrated 3 phase home battery deployment can be a cost-effective lever. Centralised is cleaner for systemic, large MW needs. Hybrid often wins on flexibility.

Step 3 — Control, aggregation and software requirements

Mitigating curtailment is mostly a control problem. You need a battery management system (BMS) plus orchestration software that can respect network constraints, state-of-charge (SoC) windows and market dispatch signals. Inverter coordination matters too — latency, telemetry and ramp rates determine whether a battery can respond to a sudden constraint. Don’t skimp on communications architecture; a flaky telemetry stream will turn a clever control algorithm into guesswork. —

Step 4 — Commercial and regulatory playbook

Design commercial models that align incentives. Options include capacity payments to aggregators, constraint-based dispatch triggers, or locational marginal pricing mechanisms. You’ll want clear settlement logic for when batteries relieve a constraint versus when they’re providing energy. Regulatory clarity on export limits, behind-the-meter participation and frequency response will make or break projects — and yes, you should model the avoided transmission capex as part of the business case.

Step 5 — Operational practices to reduce real curtailment

Operational rules are where theory meets reality. Practical tactics include:

  • Pre-emptive charging: fill batteries when local generation surplus is forecasted.
  • Staggered dispatch: avoid synchronised injection that hires voltage excursions or hits protection settings.
  • Fast response reserves: reserve a margin of SoC for unexpected grid events.

These approaches rely on good forecasting, fast telemetry and agreed safety margins with the network operator.

Common mistakes and how to dodge them

Teams often assume one silver-bullet option. Typical errors are undersizing the soak capacity, ignoring inverter response times, or failing to plan for rounds of firmware updates in deployed distributed units. Another frequent slip: treating distributed assets as passive — they need active orchestration and contractual clarity. Fixes are pragmatic: prototype the control stack with a pilot, stress-test with real data, and lock in acceptance tests for SoC, round-trip efficiency and charge/discharge cycles.

Framework checklist: technical, commercial and operational gates

Before you sign any major roll-out, pass these gates:

  • Technical: validated BMS/inverter interoperability and latency targets met.
  • Commercial: clear revenue streams for curtailment avoidance and ancillary services.
  • Operational: dispatch playbooks, contingency margins and telemetry SLAs agreed.

Passing all three reduces surprises and helps scale deployments with confidence.

Advisory — three golden rules for selecting strategies and vendors

1) Measure, don’t guess: insist on KPIs tied to avoided curtailment (MWh) and verify with a pilot. 2) Prioritise control fidelity: latency, SoC visibility and standardised APIs beat feature lists in the long run. 3) Value modularity: choose solutions you can scale incrementally — mixing large BESS with aggregated home systems lowers stranded‑asset risk.

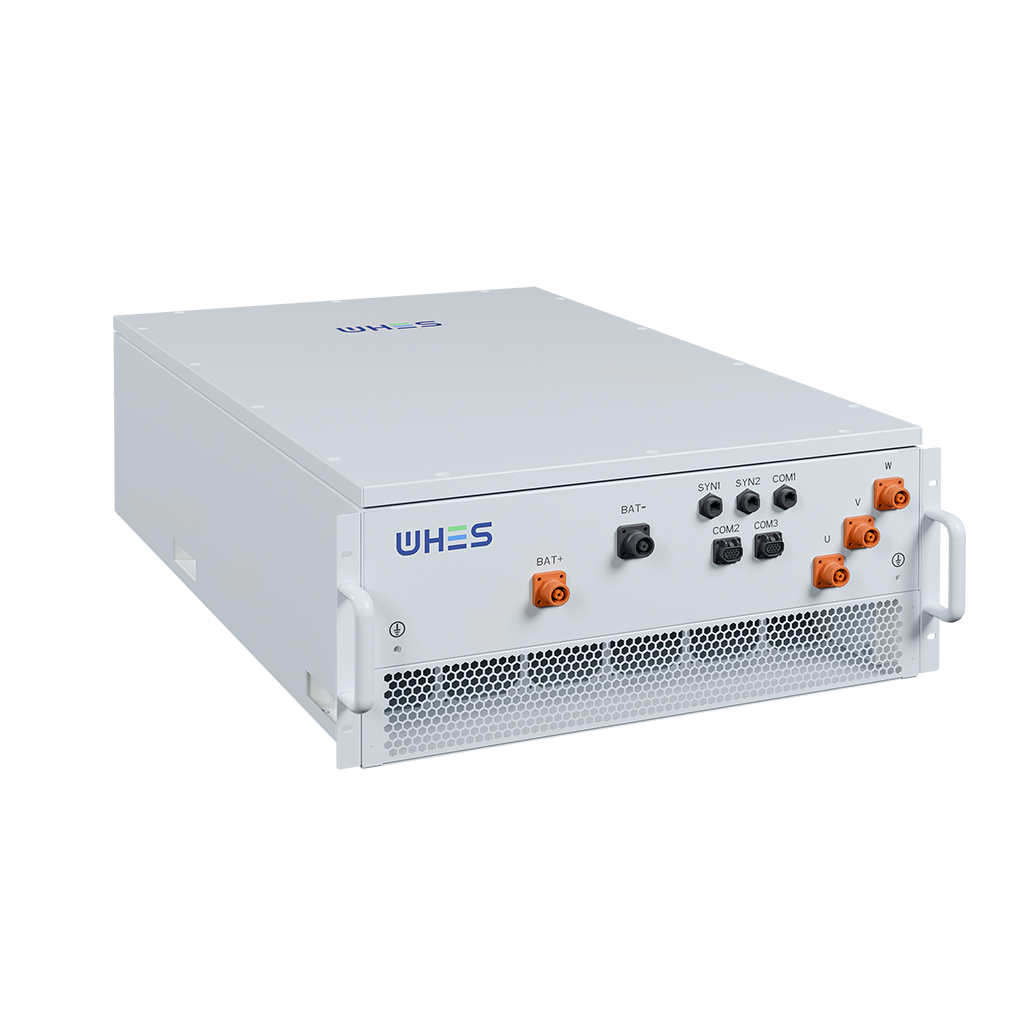
Bring these rules together and the natural endpoint is a partner that can deliver hardware, software integration and operational support — that’s where a company like WHES can fit into your rollout, offering modular systems and integration know-how that turn a framework into on-the-ground outcomes. —

June 28, 2026 0 comments
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • What Is an Automated Parking Management System? A Practical Guide for Buyers
  • How to compare options when choosing undermount kitchen sinks
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take
  • OEM CNC Prototyping: Turning Concepts into Production-Ready Parts
  • The Romantic Evolution of Your Camera Bag: From First Kiss to Lifetime Companion

Recent Comments

No comments to show.

About Me

About Me

Hi, my name is Mike, a freelancer who love to work from anywhere. I share my journey and tips on how to start freelance on my Blog. Enjoy!

Keep in touch

Facebook Twitter Instagram Pinterest Youtube Email

Popular Posts

  • 1

    Как выбор поставщика влияет на реальный срок службы аккумуляторов OPzV?

    October 19, 2025
  • 2

    Эволюция счетно фасовочных машин: Упаковка таблеток на новом уровне

    September 8, 2025
  • 3

    Неожиданные выгоды аккумулятор DIN EN в реальной эксплуатации? Сравнение без маркетинга

    September 5, 2025
  • 修復短路還是精準重建?比較洞見:現代牙齒矯正的選擇與前瞻

    November 3, 2025
  • 5

    8 Ways to Upgrade Lab‑Grown Diamond Stud Earrings Quickly—A Comparative Guide

    November 5, 2025
  • 6

    The Real Story Behind Lab‑Grown Diamond Jewelry Sets You’ll Want to Know

    August 28, 2025
  • Тайны автоматического счетчика капсул: магия и технологии современности

    November 14, 2025

Categories

  • Business (150)
  • Featured (6)
  • Freelance (21)
    • Guide & Tips (7)
    • Start (7)
    • Tools (7)
  • Global Trade (171)
  • Industry (161)
  • Market (169)
  • Tech (156)

Recent Posts

  • What Is an Automated Parking Management System? A Practical Guide for Buyers

    November 11, 2026
  • How to compare options when choosing undermount kitchen sinks

    November 10, 2026
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take

    November 9, 2026

Featured Posts

  • 6 Free Graphic Design Invoice Templates

    January 26, 2019
  • 10 Tools For Better Documents Editting

    January 26, 2019
  • 5 Gears A Freelancer Should Own

    January 26, 2019

Guides & Tips

  • What Is an Automated Parking Management System? A Practical Guide for Buyers

    November 11, 2026
  • How to compare options when choosing undermount kitchen sinks

    November 10, 2026
  • Active RFID Tag Range Sourcing: Cost, Lead Time and Quality — a Kiwi Problem-Driven Take

    November 9, 2026
  • Facebook
  • Twitter
  • Instagram
  • Pinterest
  • Youtube
  • Email

All Right Reserved. Designed and Developed by cornerbrickmc.